User-agent group 1
User-agent group 2
robots.txt
User-agent: *
Disallow: /admin/
Disallow: /cart
Disallow: /*?sessionid=
Allow: /admin/public/

User-agent: GPTBot
User-agent: ClaudeBot
User-agent: CCBot
Disallow: /

Sitemap: https://example.com/sitemap.xml
Upload this to the root of your domain so it is served at /robots.txt.
Validation
0 errors · 1 warning- Line 10: `Disallow: /` blocks the whole site for "GPTBot, ClaudeBot, CCBot". That is intentional when refusing a specific crawler - just confirm it is the agent you meant.
Test a URL
The longest matching path pattern wins, and Allow beats Disallow on a tie - the same precedence real crawlers use.
Known crawlers
Click Block to add a group that refuses a crawler outright. Compliance is voluntary - this stops cooperative bots, not scrapers.
| Token | What it is | Action |
|---|---|---|
| Googlebot | Google Search's main web crawler. Blocking it removes you from Google over time. | |
| Googlebot-Image | Crawls images for Google Images. Block it to keep photos out of image search. | |
| Bingbot | Microsoft Bing's crawler. Also feeds Bing-powered results in other products. | |
| DuckDuckBot | DuckDuckGo's own crawler for its instant answers and index. | |
| Baiduspider | Baidu's crawler, the dominant search engine in China. | |
| YandexBot | Yandex's crawler, the leading search engine in Russia. | |
| Slurp | Yahoo's legacy crawler. Still used for some Yahoo verticals. | |
| Applebot | Apple's crawler, powering Siri and Spotlight Suggestions. | |
| Twitterbot | Fetches link preview cards for X/Twitter. Blocking it kills your share previews. | |
| facebookexternalhit | Fetches Open Graph previews for Facebook, Messenger, and WhatsApp. | |
| GPTBotAI | OpenAI's crawler that collects public web content used to train its models. | |
| ClaudeBotAI | Anthropic's crawler for gathering training data for Claude. | |
| PerplexityBotAI | Perplexity's crawler, used to index pages its answer engine cites. | |
| CCBotAI | Common Crawl's bot. Its public corpus is a common source of AI training data. | |
| Google-ExtendedAI | Controls whether Google may use your content for Gemini and Vertex AI training. It does not affect Google Search ranking or indexing. | |
| BytespiderAI | ByteDance's crawler, associated with TikTok and its AI products. | |
| anthropic-aiAI | Legacy Anthropic token. Harmless to keep alongside ClaudeBot for older references. |
robots.txt ジェネレーターとは何ですか?
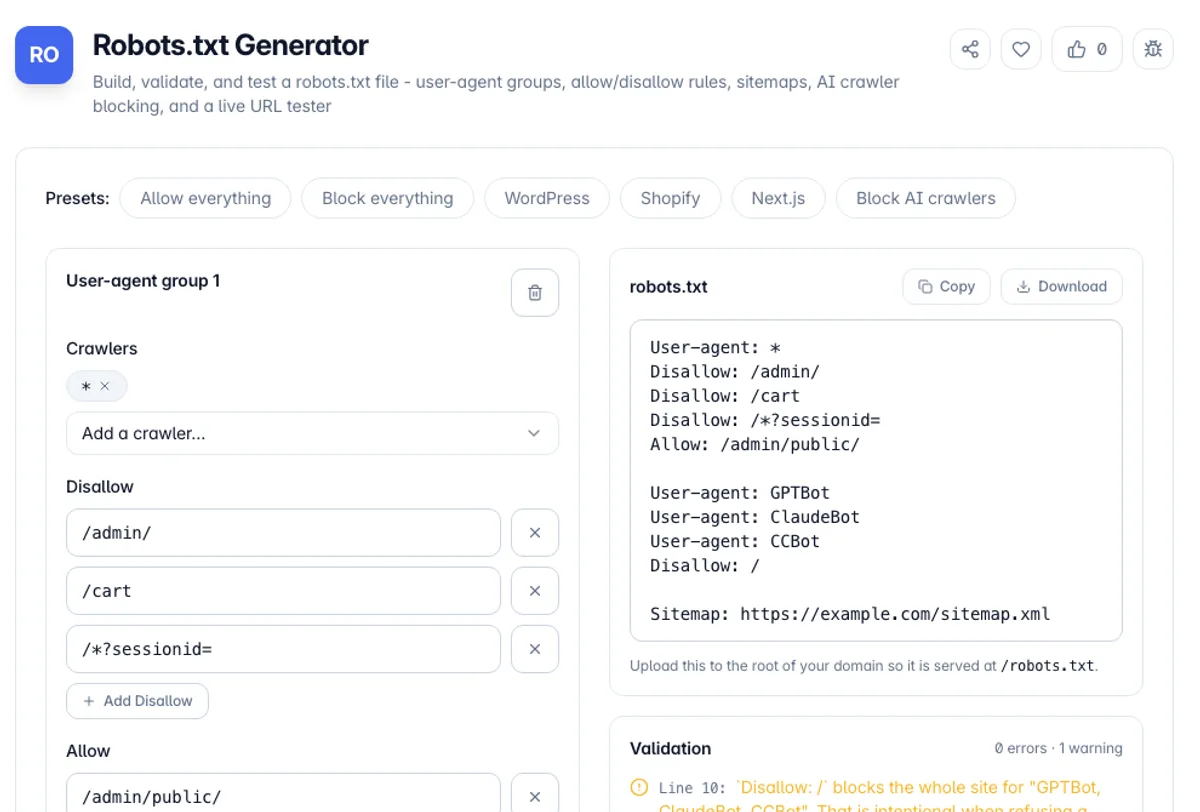
robots.txt ジェネレーターは、ドメインのルートにあるプレーンテキスト ファイルを構築し、サイトのどの部分をフェッチするかをクローラに知らせます。 `user-agent:` 行の後に `allow:` と `disallow:` ルールが続く ` ` ` ` ` と `disallow:` が続く ' 行のように見える ただ、ルールはグループ内でのみ適用されます、パスはスラッシュで始まり、`*` と `$` は特定の方法で動作し、`ser-agent: /` の下で `user-agent: *` は、サイト全体を Google から引き出すことができます。 このツールは構造化された形式からファイルを構築するため、構文は構造によって正しいです。
世代を超えて 3 つの仕事をします。 ファイルをリンクし、実際のフットガンにフラグを立てます。グループの外に出ているルール、相対パス、「すべてを許可する」という裸の「disallow:」、絶対に「すべてを許可する」、絶対的ではない、不明なディレクティブではない、ブランケット ブロックの外に出るルール。 既存の robots.txt を編集可能なグループに戻し、現在ライブのものを貼り付けて修正できます。 また、実際のクローラが使用するのと同じ最長一致の優先順位で、ルールに対して URL をテストします。最も具体的な一致パターンが勝ち、ビートが引き分けで許可されないようにすることで、展開前にページに到達できることを証明できます。
はっきり言ってもらうべきことの 1 つ: robots.txt は、インデックス作成ではなくクロールを制御し、セキュリティの境界ではありません。 他のページがリンクされていても、ブロックされた URL は、フェッチしたことのない URL をインデックス化できるため、検索結果に表示される可能性があります。 ページをインデックスから除外するには、「noindex」メタ タグまたは X-Robots-Tag ヘッダーが必要です。これは、クローラーがページをフェッチすることが許可されているかどうかだけを確認できます。 ファイルは公開されています。/robots.txt で誰でも自分のファイルを読むことができるので、そこに秘密のディレクトリをリストすると、それをアドバタイズします。 プライベートなものには認証を使用します。
robots.txt ジェネレーターの使い方
プリセットから始めるか、現在のファイルを貼り付けます
プリセットを選択 - すべて許可、すべてをブロック、WordPress、Shopify、Next.js、または AI クローラをブロック - フォームをワンクリックで埋めるか、Live robots.txt を貼り付けて編集可能なグループに戻します。
ユーザー エージェント グループを構築する
クローラーまたはクローラーのセットごとにグループを追加し、既知のボット リストから選択するか、トークンを入力します。 各グループに許可を与えてパスを許可し、目的のエンジンが 1 つをターゲットにしている場合は、クロール遅延を与えます。
サイトマップを追加してバリデーターを読む
1 つ以上の絶対サイトマップ URL を追加します。 バリデーターはすべてのキーストロークで実行され、エラー、警告、および行番号付きのメモを報告します。出荷前に赤色のものを修正します。
URL をテストしてから、コピーまたはダウンロード
パスとユーザー エージェントを入力して、許可または許可されていないことを確認し、正確にどのルールで決定したかを確認します。 期待どおりに動作したら、ファイルをコピーするか、robots.txt をダウンロードして、ドメイン ルートにアップロードします。
主な機能
最も長い一致の URL テスター
RFC 9309 の優先順位を使用して、任意のユーザー エージェントに対してパスをテストします。最も一致するパターンが勝ち、タイの引き分けを許可します。これを決定した正確なルールを指定します。
組み込みのバリデータ
グループ外のルール、相対パス、空白の許可しない行、絶対的なサイトマップ URL、不明なディレクティブ、およびブランケットの禁止をキャッチします。 / サイトのインデックスを外します。
ワンクリックプリセット
すべてを許可、すべてをブロック、WordPress、Shopify、Next.js、ブロック AI クローラーはそれぞれフォーム全体に賢明で正しい開始点を入力します。
AI クローラー コントロール
GPTBOT、Claudebot、PerplexityBot、CCBot、Google-Extended、ByteSpider、Anthropic-AI をワンクリックでブロックして、検索エンジンを完全に歓迎します。
Frequently Asked Questions
Related Tools
Hreflang Generator
Free hreflang generator for multilingual and multi-region sites - build hreflang tags as HTML link tags, XML sitemap entries, or an HTTP header. Validates codes and x-default. Runs client-side.
htaccess Redirect Generator
Generate Apache .htaccess 301 and 302 redirect rules from a list of old-to-new URLs, plus force-HTTPS and www canonicalization directives, all in the browser.
Domain Search
Check one name across dozens of TLDs at once. RDAP first, WHOIS fallback, and a verdict of available, taken or unknown, never a guess
Maps Scraper
Pull business listings for any search and place: name, address, category, rating, review count, phone and website, deduplicated and exportable as CSV.
Comments
0 comments
No comments yet. Be the first to share your thoughts!